Imagine a regular customer who needs to reorder a product. They type the supplier’s name into a search engine, click the first sponsored result, and complete the purchase. The advertising dashboard records a conversion and assigns revenue to the campaign.
The record is accurate about the route. It leaves another question unanswered: would the customer have purchased through an unpaid result, a saved link, or another route if the advertisement had not appeared?
That missing comparison matters when the company allocates its next growth budget. A campaign can sit close to a purchase and receive credit for it while changing very little about whether the purchase happens.
The distinction becomes useful when leadership begins asking advertising to account for the business it adds, as well as the transactions it touches.
Attribution and additional demand answer different questions
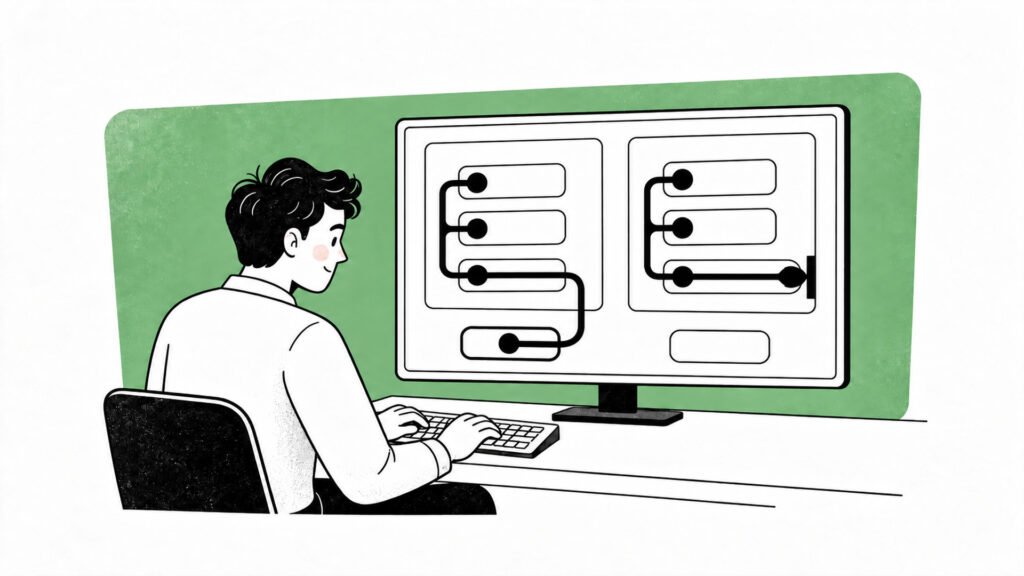
Attribution assigns credit among recorded interactions. It helps teams understand observed customer journeys and manage activity across channels. Incrementality estimates how outcomes differ because an intervention occurred.
The first approach can show that a buyer clicked an advertisement before purchasing. The second needs a credible estimate of what would have happened without that advertisement. The two measures may agree reasonably well in some settings and diverge sharply in others.
The problem is especially easy to miss when a campaign targets people already likely to buy. A regular customer, a recent website visitor, or someone searching for a precise product may convert at a high rate. That makes the audience attractive in a performance report. It does not establish how much the advertising changed its behavior.
The business still benefits if an advertisement provides information, brings a purchase forward, or prevents a buyer from choosing an alternative. Those effects need to be measured in the appropriate context. Proximity to a sale cannot establish them on its own.
A familiar brand can pay for a route customers would replace
Researchers Thomas Blake, Chris Nosko, and Steven Tadelis examined this problem through large field experiments at eBay, published in Econometrica in 2015. They found that conventional estimates substantially overstated the returns from paid search in that setting.
Brand-keyword advertisements produced no measurable short-term benefit in the experiment. For non-brand keywords, the effects differed across customers: new and infrequent users responded more positively, while frequent users accounted for much of the expense without a corresponding change in purchasing behavior.
The result does not support a rule to turn off every campaign targeting a brand’s own name. eBay was an established marketplace, the research measured particular interventions, and competition and buying behavior vary. The enduring lesson is the distinction between customers who use an advertising route and customers whose behavior changes because that route exists.
For a smaller or less familiar business, paid search may provide discovery or reassurance that an existing customer of a major marketplace does not need. The appropriate response is to test the assumption in the business’s own circumstances.
More detailed data does not automatically solve the problem
An advertising team may try to correct measurement by adding more customer characteristics, extending the attribution window, or using a more elaborate model. These changes can improve analysis, but they do not automatically reveal the missing comparison.
A study by Brett Gordon, Florian Zettelmeyer, Neha Bhargava, and Dan Chapsky compared observational methods with 15 randomized advertising experiments on Facebook. The researchers found that the observational approaches often failed to recover the experimental effects despite extensive individual-level data. Errors could overstate or understate effectiveness.
The issue is causal identification. If people exposed to an advertisement differ from those who are not exposed in ways related to purchasing, comparing their conversion rates can confuse those differences with advertising’s effect. A more sophisticated description of the exposed group may still leave relevant differences unmeasured.
The commercial implication is that measurement quality depends on the design of the comparison. It cannot be inferred from how detailed or technologically advanced a dashboard looks.
The same report can imply very different economics
Consider a deliberately simplified example, not a company case.
A campaign costs $10,000 and receives credit for $100,000 in revenue. Its reported return on advertising spend is ten to one. A well-designed experiment then estimates that only $20,000 of revenue was additional to what would otherwise have occurred.
At a 40 percent contribution margin before media costs, that additional revenue contributes $8,000. After the $10,000 campaign cost, the measured period shows a $2,000 shortfall. The calculation assumes that the margin already accounts for relevant variable delivery costs and that later customer value is outside the measured period.
The campaign’s attributed revenue has not changed. The investment decision has.
There may be a case for continuing if those additional customers produce sufficient future contribution. That case needs evidence about subsequent behavior, rather than a return to the original attribution figure. The example demonstrates why revenue credit, incremental revenue, and incremental contribution deserve separate attention.
It also changes the question asked of a promising audience. A group with a lower conversion rate could be a better investment if advertising changes more purchases within it, at an acceptable cost. Finding likely buyers and influencing buyers are related but different commercial tasks.
Build the comparison before changing the budget
Where feasible, an experiment can randomly assign eligible customers to groups with different advertising treatment, including a holdout that does not receive the campaign being evaluated. Random assignment creates a basis for comparison before customers select themselves into exposure or clicking.
Some businesses must work at a geographic level instead. Such a design needs sufficient comparable markets, attention to differences in demand, and controls for other changes. Pausing advertisements in one region and comparing it casually with another does not make the result causal.
This approach remains part of the current measurement discussion. Google included geographic incrementality and causal measurement in its 2026 advertising measurement agenda. That is a vendor’s account of its tools and direction, rather than independent evidence that any implementation will produce a reliable result.
Before a test begins, define the decision it must inform. Specify the outcome, measurement horizon, and size of effect that would justify changing expenditure. Use business-level purchases or contribution where appropriate, so a shift from paid traffic to an unpaid route is not mistaken for a lost sale.
The design also needs enough observations to distinguish a commercially meaningful effect from normal variation. An inconclusive result should remain inconclusive. Lack of statistical precision is not proof that a campaign has no value.
Match the measurement to the job of the spending
Advertising can affect more than an immediate transaction. It can influence later demand, shift purchases between channels, or affect which brand a customer considers. A short experiment cannot settle every long-term question.
These limitations matter in both directions. A narrow measurement window can miss later benefits. A broad claim about brand building can also shelter expenditure from examination indefinitely. The business should state the expected mechanism and choose a time horizon that could reasonably observe it.
Channel interactions require similar care. A campaign may create interest that another channel eventually captures. Multiple platforms may assign themselves credit for the same purchase. Measuring one platform’s reported conversions in isolation cannot resolve the total effect on the company.
Budget scale is another boundary. Evidence that a campaign contributes at its current spend does not establish that the next increase will be equally productive. The next customers reached may differ, and the cost of reaching them may rise. Material spending increases deserve renewed scrutiny.
Let the evidence change a specific decision
A useful measurement program starts with expenditure large enough, uncertain enough, and adjustable enough for better information to matter. It might examine a mature retargeting audience, a branded-search campaign, or a proposed expansion in spend. The choice should follow the business’s actual exposure.
Leadership can then decide whether to maintain, reduce, redirect, or test a different level of investment. The result may protect a campaign that looked weak under attribution, just as readily as it may challenge one with an impressive reported return.
The next budget discussion should therefore include an estimate of what would change if the proposed spending were removed or increased, together with the uncertainty around that estimate. Where the evidence is weak, a bounded test may be the most useful investment available.
This gives finance and marketing a shared basis for judgment: the additional business expected from the expenditure, the contribution it could produce, and the evidence that would justify another commitment. Reported campaign credit remains useful, but it no longer has to carry a claim it cannot establish on its own.